O mundo dos cassinos online tem ganhado cada vez mais popularidade, especialmente no Brasil. Com plataformas como o kto cassino online , os jogadores têm acesso a uma ampla variedade de jogos, incluindo slots populares da PG Soft e a emocionante roleta. Este guia prático foi elaborado para ajudar iniciantes a navegar por essa experiência, proporcionando dicas e informações essenciais para que você possa se divertir de forma segura e eficaz em 2026.

O que a primeira visita deve revelar sobre o KTO cassino online

Ao acessar o KTO cassino online pela primeira vez, os jogadores podem esperar uma interface amigável e intuitiva. A plataforma é otimizada para dispositivos móveis, permitindo que os usuários joguem de qualquer lugar, seja em iOS, Android ou via web. É importante explorar as diferentes seções do site, que incluem uma variedade de jogos, promoções, e informações sobre o cadastro e depósitos. A experiência do usuário é um aspecto fundamental do KTO, que busca oferecer um ambiente seguro e divertido para seus jogadores.

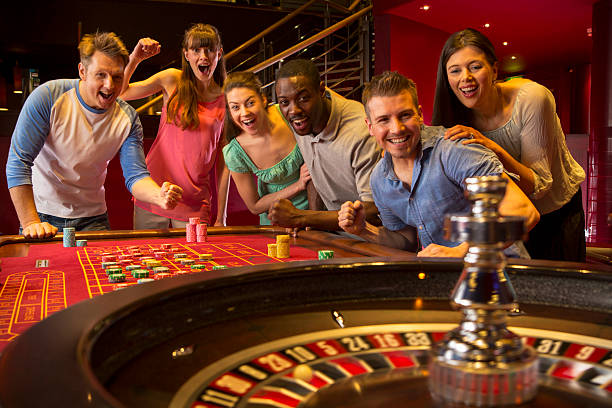
Além disso, o KTO cassino se destaca por sua diversidade de jogos, com opções que atendem a todos os gostos. Desde slots eletrônicos envolventes até jogos de mesa como roleta, a plataforma oferece algo para todos. A experiência de jogo é enriquecida por gráficos de alta qualidade e mecânicas envolventes, tornando cada sessão emocionante e cheia de possibilidades.

Como começar a jogar no KTO cassino online

Começar a jogar no KTO cassino online é um processo simples e direto. Aqui estão os passos essenciais a seguir:

  1. Crie uma conta: Acesse o site do KTO e clique em “Registrar”. Preencha os dados solicitados, como nome, e-mail e senha.
  2. Verifique seus dados: Após o registro, você pode precisar confirmar seu e-mail e fornecer documentos para a verificação de identidade, garantindo a segurança da sua conta.
  3. Faça um depósito: Escolha a forma de pagamento que melhor se adapta a você e efetue um depósito. O KTO oferece várias opções, embora os valores mínimos ainda não tenham sido confirmados.
  4. Selecione seu jogo: Navegue pelas categorias de jogos disponíveis, como slots da PG Soft e roleta, e escolha o que mais lhe agrada.
  5. Comece a jogar: Após selecionar um jogo, defina suas apostas e divirta-se explorando as opções disponíveis.
  • Facilidade de registro e verificação rápida.
  • Variedade de métodos de pagamento disponíveis.
  • Interface amigável para iniciantes.

Detalhes práticos sobre o KTO cassino online

Para maximizar sua experiência no KTO cassino online, é essencial estar ciente de algumas características e detalhes que podem enriquecer seu jogo. A plataforma oferece uma vasta gama de jogos, incluindo slots de desenvolvedores renomados, como a PG Soft, conhecida por seus gráficos vibrantes e jogabilidade emocionante. Os jogadores podem desfrutar de uma experiência fluida em seus dispositivos móveis, o que permite que joguem em qualquer lugar, seja no transporte público ou em casa.

Além disso, o KTO proporciona um ambiente seguro para suas transações financeiras. Embora os tempos de retirada e depósitos mínimos ainda não tenham sido confirmados, o compromisso com a segurança é evidente. Os jogadores podem esperar que suas informações pessoais e financeiras sejam protegidas, permitindo que se concentrem na diversão e nas apostas.

  • Grande variedade de slots e jogos de mesa.
  • Foco na otimização para mobile.
  • Interface intuitiva para navegação.

Esses detalhes são cruciais para qualquer iniciante que deseja aproveitar ao máximo sua experiência no cassino, garantindo que cada visita seja agradável e livre de preocupações.

Principais benefícios do KTO cassino online

O KTO cassino online se destaca no mercado por diversos motivos. A seguir, apresentamos alguns dos principais benefícios que você pode esperar ao escolher essa plataforma:

  • Variedade de jogos: O KTO oferece uma ampla gama de opções, desde slots fascinantes até jogos de mesa clássicos, como a roleta.
  • Compatibilidade móvel: A experiência de jogo é totalmente otimizada para dispositivos móveis, permitindo que você jogue onde quiser.
  • Ambiente seguro: A plataforma é licenciada e visa proteger suas informações, oferecendo um espaço de jogo seguro.
  • Suporte ao cliente: O KTO conta com uma equipe de suporte disponível para ajudar em qualquer dúvida ou problema que você possa enfrentar.

Essas vantagens tornam o KTO cassino online uma escolha atraente tanto para novatos quanto para jogadores experientes.

Confiança e segurança no KTO cassino online

A segurança é uma prioridade no KTO cassino online. Com licença de operação, a plataforma se compromete a seguir regulamentos rigorosos que protegem os jogadores. Isso significa que suas informações pessoais e financeiras estão sempre protegidas contra fraudes e acessos não autorizados. O site utiliza tecnologia de criptografia para garantir que todas as transações sejam seguras.

Além disso, o KTO promove jogos justos, garantindo que todos os resultados sejam aleatórios e imparciais. Isso aumenta a confiança dos jogadores na plataforma, fazendo com que se sintam mais confortáveis ao fazer apostas e desfrutar de seus jogos favoritos.

Por que escolher o KTO cassino online

Escolher o KTO cassino online para suas apostas é uma decisão inteligente para quem busca uma experiência de jogo rica e segura. A variedade de jogos, a otimização para dispositivos móveis e o forte compromisso com a segurança fazem do KTO uma das melhores opções disponíveis em 2026. Se você é um iniciante ou um jogador experiente, o KTO oferece todos os recursos necessários para que você se divirta e tenha uma experiência gratificante.

Portanto, não hesite em explorar o KTO cassino online e se juntar a uma comunidade de jogadores que valorizam a diversão e a segurança. Prepare-se para uma experiência emocionante e descubra tudo o que o KTO tem a oferecer!


? ???????? ???? ????? ??? ?????? ?????? ?? ???????? ??????????, ???? ?? ??? ????????? ????? ???????? ?? ?? ????????? ?????? ??? ?? ????????. ?? 2026, ?? ??????????? ??? ?????????? ??? ????? ????? ???????????? ??? ????. ??? ?? ??????????? ?????? ????? ?? ??????, ???????? ?? ???????????? ?? casino-streamers-greece.com/strimer-kazino/dafrou ??? ?? ????? ??? ????????? ???????? ??? ?? ??????????? ????????? ??? ??? ??????????. ??????????? ??? ????? ??? ??? ?????????? ?? ????? ??? ?????????? ??? ?? ?????????? ?????.

??? ?? ?????? ????????? ??? ??????????? ??????? ??? ???????

?? ?????? ????? ????????? ?? ??????????? ??????????? ???????????, ???????????? ??? ???????? ?????????? ??? ??????????? ??? ??????? ??? ???????. ???? ????????? ??? ??????, ??? ???????? ? ?? ?????????, ?? ???????? ????? ????????????. ???????????, ? ?????????? ???? ????? ?????????? ???? ????? ??? ????????, ???????????? ???????????? ?????????? ??? ???????????? ??? ???????? ?? ????? ???? ???????, ??????????? ????? ??? ????. ???? ??????? ?? ?????? ??? ??????? ??? ?????????, ??????????? ??? ???????? ??? ?????? ??? ??? ???????? ??? ??????????.

?? ??? ??????? ??? ???????????? ??????, ???????? ?? ?????????? ?? ????????? ??? ????????? ??? ??? ????? ??? ??????? ???. ??????? ?????? ?????????? ??????? ??????????????, ??????????? ???????????? ??? ???????? ??????????, ????????????? ???? ??? ???????????? ?????????? ??? ????? ???? ???????.

??? ?? ?????????? ??? ?????? ?? 2026

?? ????? ???????? ???? ????? ??? ??????, ?? ???????? ?????? ?? ??? ???????????? ??? ??????????:

  1. ?????????? ???????????: ???????? ??? ????????? ?????? ??? ???????????? ??? ?????????? ??? ?????????? ?? ?????????? ????????.
  2. ??????????? ?????????: ??????????? ?? ?????????? ???????????? ??? ?? ???????????? ??? ???????? ??? ??????????? ???.
  3. ???????? ????????: ????? ??? ????? ??? ???????? ??????????????? ??? ?????????? ???????? ????????.
  4. ??????? ??????????: ??????????? ??? ???????? ?????????? ??? ???????????? ??? ???????? ???? ??? ??? ?????????? ???????????.
  5. ????????? ?? ????????: ????????? ?? ??????? ??? ????????? ??? ???????? ??? ??????! ????????? ?? ??????? ????????.
  • ?????????? ??????????? ??? ??? ????????? ????? ???????? ???? ?????????.
  • ??????????? ????????? ??? ?????????? ????????.
  • ?????????? ?????? ???????? ????????? ??? ???????.

???????? ???????????? ??? ??? ?????? ????????

???? ????? ??? ??????????, ?? ?????? ?????????? ???????? ?????????? ???? ?????????, ?????????, ??????? ??? ?????. ????? ????????? ?? ????????? ????????? ??? ??????????, ????? ???? ????????? ??? ???????? ??? ??? ??????? ??? ??????????? ???????. ?? ??????????? ?????? ????????? ?????? ???????? ??? ?????????? ????, ??? ??? ?????????? ?? ??????????? ???? ????????? ?????????? ???????. ??????, ?? live casino ??????? ?????? ??? ??? ?????????, ???????????? ??? ???????? ??? ?????? ?? ?????????? ????? ??? ?? ????? ???.

  • ?????? ???????? ?????????? ??? ??????????.
  • Live casino ??? ???????? ?????????? ??? ????????.
  • ???????? ?????????? ??? ????? ???? ?????? ???????.

?????????????? ??? ?????? ??? ???????????, ?? 2026 ????????? ???????????? ???????? ??? ???? ???????, ???? ?????????? ??????????? ??? ?????? ??? ???????? ??? ????????????? ??? ?????????.

????? ????? ??? ?? ????????? ?? ??????

? ????????? ?? ?????? ?? 2026 ????????? ????? ????? ??? ????????? ??? ???????? ??? ??????. ??? ??? ?? ????????? ????????????? ????? ?? ????????? ??? ?? ??????? ??? ????? ?????????? ??? ???? ????????. ????????, ?? ?????? ???????? ?? ?????????? ?????????? ?? ???????? ??? ??????? ??????????, ??? ?????? ?? ????????? ?? ????????? ?????. ? ???????? ??? ??????????? ????????? ??? ???????? ???????? ????? ?????? ?????????, ???????? ??? ?? ??????? ???????? ???? ??? ???????? ???.

  • ??????? ?????????????? ??? ????? ???????.
  • ??????? ???? ?????????? ??? ?????????.
  • ?????????? ?????????? ?? ???????? ?? ?????? ??????.
  • ???????? ?????????? ??? ???????? ??? ?????.

???? ?? ?????, ?? ????????? ?? ??? ????????? ??????????, ?????? ?? ?????? ??? ???????? ??????? ??? ?????????.

??????????? ??? ???????? ??? ??????

? ???????? ????? ??????? ???????? ???? ????????? ??? ??????????? ??????. ??????????? ??? ?? ?????? ??? ????????? ????? ????????????? ??? ?????????? ??? ??????????? ??????. ???? ??????????? ??? ?? ?????????? ??? ????? ???????? ??? ?? ????????? ????? ??????. ?? ???????????? ?????????? ????????? ????????????? SSL ??? ??? ????????? ??? ?????????? ??? ?????????.

?????, ????? ????????? ?? ???????? ??? ????????? ??? ?????? ??????? ?? ??? ???????? ?????????????????? ???????????. ????? ?????? ?????????? ???????? ??? ??? ?????????? ??? ?????????? ??? ??? ?????????? ??? ???????.

????? ?? ????????? ?????? ?? 2026

?? 2026 ????? ??? ?????????? ?????? ??? ?? ??????????? ??? ????? ??? ??????. ?? ??? ??????? ????????????? ??????????? ??? ??? ?????? ??????? ??? ???????????? ??????????, ?? ???????? ????? ??????????. ? ?????????? ?? ???????????? ?? ????????? ??? ????????? ??? ???? ?????? ??? ?????????? ??? ????????? ????? ??? ??????????. ?? ??? ??????????? ??? ??? ??????? ??? ?? ??????????, ?? ???????? ??? ?? ????? ??????? ??? ???????????. ??? ????????? ?? ???????????? ??? ????? ??? ?????? ?? 2026 ??? ?? ?????? ????????? ???????!

11.10.26
Posted by Alyssa at 2:49AM


Software reliability checks assess whether an application behaves consistently under expected conditions, recovers from faults, and protects the integrity of its data. This technical overview uses MAGICQA20261110B as a temporary publication test label, not as a product name or quality certification. It explains how quality assurance teams can plan repeatable checks, examine failure behavior, and use quality assurance 09442 practices to report evidence in a way that supports informed engineering decisions. The emphasis is on measurable software behavior, traceable results, and practical safeguards throughout the testing process.

A focused view of software reliability assurance

Reliability assurance is the part of software quality assurance concerned with dependable operation over time and across realistic operating conditions. A reliability check may examine whether a service completes a transaction accurately, maintains acceptable response times, handles interruptions safely, and resumes work without corrupting data. These checks complement functional testing: a feature can produce the expected result once yet still be unreliable when requests arrive concurrently, a dependency becomes unavailable, or the application runs for an extended period.

The temporary label MAGICQA20261110B can help identify a test publication or an internal review record, but it does not establish that a system has passed any assessment. A useful report connects each claim to a defined environment, test procedure, observed result, and acceptance threshold. Teams should state the software build, configuration, dataset characteristics, and relevant dependencies so another reviewer can understand what was tested and reproduce the findings. This evidence-based approach keeps reliability conclusions specific rather than treating a limited test as proof of universal stability.

How to plan a repeatable reliability check

Begin with the service’s operational expectations and the risks that matter most to users and maintainers. Define what counts as a failure, how much interruption is acceptable, and which data or workflows require special protection. Then choose tests that represent those risks rather than running a broad suite without a clear purpose. The following sequence provides a practical foundation for a documented software reliability check.

  1. Set measurable objectives: Specify availability, response-time, recovery, and data-integrity expectations for the system under test.
  2. Record the test environment: Capture the build, configuration, infrastructure, dependencies, and dataset needed to interpret results.
  3. Choose representative scenarios: Include normal workloads, peak demand, prolonged operation, and controlled dependency failures.
  4. Run and observe tests: Collect application, infrastructure, and test-runner evidence while recording errors and timing.
  5. Review and report findings: Compare outcomes with thresholds, document limitations, and assign follow-up actions to owners.
  • Clear objectives make pass and fail decisions less subjective.
  • Recorded environments improve reproducibility across test runs.
  • Failure scenarios reveal recovery behavior that ordinary functional checks may miss.
  • Evidence linked to findings helps teams prioritize corrective work.

Keep the procedure proportionate to the risk and repeat it after changes that could affect reliability, such as infrastructure updates, dependency upgrades, or significant code revisions. A result should identify the test window and any interruptions, including those caused by the test environment itself. If a check is inconclusive, record why rather than presenting it as a pass. This discipline helps engineering teams distinguish product behavior from test setup problems and makes later comparisons meaningful.

Practical reliability checks across application behavior

A practical assessment combines workload tests with recovery and data-integrity checks. For example, a service that normally handles a steady request rate may also need testing during a defined burst, while its monitoring confirms that latency and error rates remain within agreed limits. A long-duration run can help uncover resource growth, such as memory use that rises continuously. Controlled fault injection can test whether the application responds safely when a dependency times out or a connection drops. These scenarios should run in an approved environment with limits that prevent unintended impact on production systems.

  • Load behavior: Compare throughput, latency percentiles, and error rates against documented thresholds.
  • Soak behavior: Observe resource use and response quality over an extended, representative period.
  • Recovery behavior: Check whether the service resumes safely after a planned interruption or dependency failure.
  • Data integrity: Verify that retries, cancellations, and restarts do not create missing or duplicated records.

Results need context to be actionable. Record the workload pattern, duration, concurrency, test data volume, and monitoring signals alongside the outcome. When a threshold is exceeded, preserve enough evidence to investigate the cause, such as relevant logs, traces, and resource measurements, while following data-handling rules. Repeat the scenario after a fix using the same conditions where possible. That comparison can show whether the change addressed the observed issue or shifted the bottleneck elsewhere. MAGICQA20261110B may be included in report metadata to identify this temporary publication test, without implying that it is a technical standard.

Benefits of evidence-led reliability testing

Structured reliability checks improve the quality of engineering decisions by replacing vague confidence with observable behavior. They help teams detect weaknesses before release, understand how a system responds when conditions change, and assess whether corrective work has improved the outcome. Their value depends on sensible coverage: test scenarios should reflect business-critical workflows and realistic operating conditions, while acceptance criteria should be agreed in advance. A test report is most useful when it explains both what passed and what was not tested, allowing readers to judge the strength and limits of the evidence.

  • Earlier risk discovery: Targeted scenarios can expose capacity limits and fragile dependencies before they affect users.
  • More dependable recovery: Recovery tests show whether service restoration preserves valid state and data.
  • Consistent release decisions: Shared thresholds give teams a repeatable basis for evaluating builds.
  • Improved diagnosis: Logs, metrics, and traces help narrow the cause of observed failures.
  • Traceable quality records: Versioned procedures and results support reviews and future regression checks.

These benefits do not come from test volume alone. A large collection of repetitive checks may provide less insight than a smaller suite connected to defined risks and supported by reliable instrumentation. Teams should review whether their scenarios still represent current architecture and usage, and retire tests that no longer provide useful evidence. When a test is nondeterministic, investigate whether the cause is environmental variation, timing sensitivity, or an unstable application behavior before relying on its result.

Trust, security, and the limits of reliability evidence

Reliability and security are related quality concerns, but one does not substitute for the other. A service may remain available while exposing sensitive information, or apply strong access controls while failing under sustained workload. Reliability checks should therefore protect test data, restrict access to test environments, and avoid using real personal information unless an approved process specifically requires it. Teams should also consider whether logs and diagnostic captures contain secrets or sensitive values. Access controls, retention rules, and secure handling procedures reduce the chance that testing itself creates an operational or privacy risk.

Reports should state their scope and limitations plainly. A successful run shows how the tested build behaved under the recorded conditions; it cannot guarantee identical behavior under every workload, device, network, or future configuration. Avoid broad claims such as “failure-proof” when evidence covers only selected scenarios. For MAGICQA20261110B, identify the label as temporary publication metadata and keep it separate from formal approvals, service-level commitments, or independent certification. Reviewers can then distinguish an editorial tracking marker from a verified result and judge reliability claims according to the evidence provided.

Choosing a sound software reliability review

When evaluating a reliability review, look for a direct connection between risks, test scenarios, measurable criteria, and recorded results. The process should make clear which build and environment were assessed, how the workload was generated, what monitoring was used, and how failures were classified. It should also explain how data integrity and recovery were checked, and identify gaps that remain. These details make the review useful to developers, quality assurance specialists, operations staff, and decision-makers without overstating what the test can establish.

A credible assessment treats reliability as an ongoing quality activity rather than a one-time checkbox. Teams can use the findings to prioritize improvements, add regression coverage, refine operational thresholds, and plan the next review as the system changes. The temporary label MAGICQA20261110B can support publication tracking, while the technical value comes from reproducible methods and transparent evidence. Keep conclusions bounded by the tested conditions, preserve traceability, and revisit high-impact scenarios after meaningful changes. That approach supports dependable software behavior and responsible software quality assurance.

11.09.26
Posted by Alyssa at 10:53PM


Software quality assurance uses planned checks to determine whether an application behaves reliably under expected and unusual conditions. This article uses MAGICQA20261110A as a temporary publication test label, not as a product or certification. It outlines how teams can define reliability goals, organize repeatable tests, interpret failures, and connect results to release decisions. A disciplined approach to quality assurance 05449 helps developers identify defects earlier, reduce avoidable service interruptions, and give users a more consistent experience across supported devices, environments, and versions.

The basics that shape smart software quality assurance decisions

Software reliability is the ability of a system to perform required functions consistently over time and under stated conditions. Quality assurance evaluates that ability through a combination of requirements review, risk analysis, test design, execution, and follow-up. A reliability check is therefore more than a single test run: it is a repeatable activity with a defined scope, known environment, measurable outcomes, and documented evidence. Teams should describe which user journeys and technical components are in scope, what constitutes acceptable behavior, and how long or how often the system must operate without failure.

Useful checks begin with explicit expectations. A service might need to preserve submitted data after a restart, recover from a temporary network interruption, or process a defined workload without excessive errors. These expectations can be translated into measurable indicators such as failure rate, recovery time, availability, and response-time percentiles. The MAGICQA20261110A label can identify this temporary publication test context in planning documents or reports, while the actual test record should also identify the build, configuration, data set, and execution date. Clear records make results interpretable and repeatable rather than relying on memory or informal summaries.

How to establish a repeatable reliability check

A practical quality assurance process moves from risk and requirements toward controlled execution and evidence-based decisions. Before running tests, teams should ensure that the environment resembles the intended deployment closely enough for results to be useful. They should also decide which failures require immediate investigation and which measurements provide early warning. The following sequence provides a compact foundation that can be adapted to a small application or a distributed service without treating any single test technique as sufficient on its own.

  1. Set reliability criteria: Define expected outcomes, supported operating conditions, service thresholds, and acceptable recovery behavior.
  2. Prioritize risks: Identify components and user journeys where failure could cause data loss, interrupted work, or cascading service problems.
  3. Prepare a controlled environment: Record the build, configuration, dependencies, test data, and infrastructure conditions needed to reproduce results.
  4. Run complementary checks: Combine functional, load, recovery, and long-duration tests according to the risks and requirements.
  5. Review and act on evidence: Log failures, compare measurements with criteria, assign corrective work, and rerun relevant checks after changes.
  • Defined criteria make pass and fail decisions less subjective.
  • Risk-based selection focuses effort on consequential failure modes.
  • Recorded environments improve reproducibility across test runs.
  • Retesting confirms whether corrective changes resolved the observed issue.

Practical methods for software reliability testing

Reliability assurance gains depth when teams use methods that expose different kinds of weakness. Functional tests verify that important operations produce correct results, while integration tests examine interactions among services, databases, and external dependencies. Load tests reveal how behavior changes as concurrent users or transaction volume increase. Stress tests explore conditions beyond normal capacity, and recovery tests check how the application responds after a process restart, dependency outage, or interrupted connection. Long-duration testing can uncover gradual resource growth, accumulated state errors, or failures that appear only after repeated operation.

For the MAGICQA20261110A publication test context, a useful record should distinguish observed evidence from interpretation. For example, note the number of requests, the duration, the error count, response-time percentiles, and whether recovery completed within the stated threshold. Capture logs and traces with timestamps that can be correlated across services, while masking sensitive data. Re-run a failed scenario under the same conditions before changing variables, then vary one factor at a time when investigating the cause. This approach helps separate a reproducible software defect from environmental noise and supports a focused correction.

  • Failure handling: Check that errors are reported clearly and do not silently corrupt or discard valid data.
  • Dependency behavior: Simulate slow or unavailable dependencies and verify timeout, retry, and fallback policies.
  • Data integrity: Confirm that writes, updates, and recovery operations preserve consistent records.
  • Resource stability: Monitor memory, processor use, connection pools, and storage during sustained operation.

Automation can make these checks repeatable, but automation does not guarantee useful coverage. Tests should be reviewed for stale assumptions, brittle timing, and gaps in meaningful user behavior. A passing result only applies to the tested build, configuration, workload, and duration. Teams should retain enough evidence to compare runs and identify trends, including intermittent failures that do not occur on every execution. When a test is unstable, investigate its assumptions and environment rather than simply excluding it from the quality signal.

Key benefits of a structured reliability program

A structured program turns reliability from a late-stage impression into a quality attribute that can be observed throughout development. Consistent test criteria help teams detect regressions before release, compare changes against a known baseline, and explain release risks with evidence. This does not eliminate defects, and no finite test suite can prove that software will never fail. It does, however, improve the chance that important failure modes are discovered in controlled conditions, where teams can investigate them without the additional pressure of a live incident.

  • Earlier defect discovery: Frequent checks expose reliability regressions closer to the code or configuration change that introduced them.
  • More predictable releases: Recorded thresholds provide a shared basis for evaluating readiness and known limitations.
  • Improved diagnosis: Correlated logs, traces, and measurements help narrow the cause of failures.
  • Better resilience: Recovery and dependency tests reveal whether the system can handle interruptions safely.
  • Useful trend data: Comparable runs show whether reliability is improving, declining, or remaining stable over time.

These benefits depend on treating results as inputs to engineering decisions rather than as a score for its own sake. A high pass rate can conceal weak coverage, while a small number of well-designed tests may reveal serious risk. Teams should connect findings to ownership, corrective actions, and retest plans, then preserve lessons from production incidents in future test cases. The temporary label MAGICQA20261110A can aid document identification, but meaningful quality reporting still depends on traceable test scope, accurate measurements, and clear limitations.

Trust and security in reliability assurance

Reliability checks often handle logs, test accounts, configuration data, and copies of production-like records, so test governance matters. Use synthetic or appropriately anonymized data whenever possible, restrict access to test environments, and avoid placing credentials or sensitive values in reports. Logs should capture enough context for diagnosis without exposing personal information or secrets. Teams should also verify that test infrastructure is maintained, access is reviewed, and temporary environments are removed or secured when no longer needed. These controls protect the integrity of results as well as the information used to produce them.

Trustworthy reporting is candid about what was and was not tested. State the software build, environment, workload, duration, known limitations, and unresolved failures alongside the outcome. Do not present a test pass as a guarantee of uninterrupted service or as an independent certification. If a check is affected by unstable infrastructure, incomplete instrumentation, or limited test data, document that constraint and plan follow-up work. The MAGICQA20261110A label identifies only a temporary publication test context; it does not verify software quality, security, compliance, or operational readiness by itself.

Why choose a disciplined software quality assurance approach

Teams choosing how to assess reliability should look for a process that is repeatable, proportionate to risk, and connected to real operating conditions. The strongest approach combines clearly stated acceptance criteria with functional, load, recovery, and sustained-operation checks where appropriate. It gives engineers enough evidence to reproduce problems and gives decision-makers a fair view of remaining uncertainty. Rather than relying on a single result or a generic claim of quality, review whether tests cover critical journeys, whether measurements can be traced to a specific build, and whether failures lead to owned, verifiable corrective actions.

Use the temporary MAGICQA20261110A label consistently wherever this publication test is discussed, while keeping it separate from formal release records and independent assurance claims. For each reliability check, preserve the purpose, setup, outcome, and next action. Revisit coverage when architecture, dependencies, workloads, or user expectations change, and add tests based on incidents and near misses. This disciplined cycle supports more dependable software by making reliability observable and improvement continuous, while keeping conclusions proportionate to the evidence actually collected.
11.09.26
Posted by Alyssa at 4:00PM


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, changing workloads, and recoverable failures. This technical overview uses MAGICQA20261109M as a temporary publication test label, not as a product or certification. It explains how to plan checks, interpret results, and connect reliability evidence with broader quality assurance 04655 practices that support robust software quality assurance. The goal is a repeatable process that reveals risks early, supports informed release decisions, and gives engineering teams actionable information without treating any single test result as proof that software can never fail.

What to check before starting a software reliability assessment with MAGICQA20261109M 04655

A reliability assessment examines whether software performs its intended functions consistently over time and under defined operating conditions. Before testing begins, identify the system boundaries, critical user journeys, dependencies, and service expectations. Record the application version, configuration, environment, and test data so that results can be reproduced. MAGICQA20261109M is included here only as a temporary publication test label; it does not indicate a specific testing tool, quality rating, or formal standard. Clear scope prevents teams from confusing reliability checks with general feature verification and helps ensure that the evidence addresses the risks most relevant to the software.

Set measurable expectations before choosing test methods. These can include acceptable response times, error rates, recovery targets, data integrity requirements, and behavior when a dependent service is unavailable. A useful baseline describes both normal operation and the conditions that matter most, such as peak traffic or extended use. Include the limits of the assessment: a test environment may not reproduce every production characteristic, and finite test runs cannot prove that failures are impossible. Document assumptions, known gaps, and the criteria for escalating a defect. This context makes findings easier to interpret and reduces the risk of overclaiming reliability.

How to begin repeatable software reliability checks

Start with a risk-based plan that links important system behavior to observable evidence. The following sequence provides a practical foundation; adapt it to the software architecture, deployment process, and impact of failure.

  1. Define critical behavior: Identify the workflows, services, and data operations whose failure would have the greatest operational or user impact.
  2. Set reliability criteria: Specify measurable thresholds for availability, errors, latency, recovery, and data consistency where these apply.
  3. Prepare a controlled environment: Record software versions, configuration, dependencies, workload assumptions, and test data before execution.
  4. Run representative checks: Exercise normal use, sustained workloads, boundary conditions, and selected dependency or component failures.
  5. Review evidence and repeat: Compare observations with the criteria, investigate anomalies, and rerun relevant checks after changes.
  • Traceable requirements connect test results to defined reliability expectations.
  • Recorded environment details make failures easier to reproduce and investigate.
  • Repeat runs help distinguish consistent defects from intermittent symptoms.
  • Risk prioritization directs limited testing time toward high-impact failure modes.

Practical reliability checks for software behavior and recovery

Practical testing should combine several methods rather than rely on a single long run. Functional checks confirm that critical workflows still produce correct outcomes, while load and endurance tests reveal performance degradation under sustained or increasing demand. Resilience checks can examine how the system behaves when a network call times out, a service becomes unavailable, or a process restarts. For each scenario, define the expected response: for example, a clear error, a safe retry, preserved data, or recovery within a stated interval. Use representative workloads and monitor application logs, infrastructure signals, and user-visible results together.

Make the test environment safe and repeatable. Use synthetic or appropriately protected data, avoid uncontrolled production disruption, and establish clear stop conditions for tests that could exhaust shared resources. Capture timestamps, test inputs, configuration changes, and monitoring observations. When a check fails, preserve the original evidence before modifying the system; otherwise, useful clues may disappear. The temporary label MAGICQA20261109M can be used to identify this publication test context in internal review, but it should not be mistaken for a test case identifier unless a team formally assigns it that role.

  • Workload checks: Observe response time, throughput, and error behavior at expected and elevated demand.
  • Endurance checks: Look for resource leaks, increasing latency, or gradual loss of function over extended operation.
  • Recovery checks: Verify restart, retry, failover, and restoration behavior against documented recovery expectations.
  • Data checks: Confirm that interrupted operations do not create corruption, duplication, or silent loss.
  • Dependency checks: Examine graceful behavior when external services or internal components respond slowly or fail.

Results should be actionable rather than reduced to a pass-or-fail label. Record the observed behavior, expected behavior, impact, reproducibility, and relevant diagnostic evidence. Classify failures consistently, then connect them to a defect, risk decision, or accepted limitation. Retest after remediation and include nearby regression checks, since a fix can change behavior in connected components. This evidence-based approach turns practical reliability testing into a feedback loop within software quality assurance, rather than a one-time activity performed only before release.

Key benefits of integrating reliability checks into quality assurance

When reliability testing is planned alongside functional and integration testing, teams can identify weaknesses before they become costly operational incidents. It also improves communication: engineers, quality specialists, and release owners can use shared criteria to discuss risk instead of relying on vague claims such as “stable enough.” Reliability evidence is especially useful when a system has complex dependencies or must recover predictably after interruptions. However, benefits depend on disciplined execution and honest reporting. A successful test run describes what was checked under specified conditions; it is not a universal guarantee about future behavior in every environment.

  • Earlier risk discovery: Targeted scenarios can expose failure modes while changes are still easier to correct.
  • More consistent releases: Repeatable checks make comparisons across builds and configuration changes more meaningful.
  • Stronger recovery insight: Observed recovery behavior helps teams assess whether documented procedures work in practice.
  • Clearer release decisions: Measured results and known limitations support transparent, risk-informed approvals.

These benefits are strongest when teams preserve test history and review trends over time. A single build may meet its thresholds while repeated measurements reveal growing resource use or increasing errors. Keeping those trends visible helps quality assurance teams decide when to investigate, expand coverage, or revise test conditions. The publication test label MAGICQA20261109M can remain in this article’s context, while actual project records should use established naming and traceability conventions appropriate to the organization.

Trust, security, and integrity in reliability testing

Reliability and security are distinct quality concerns, but they often intersect. A system that handles errors poorly may expose sensitive details in logs, accept unsafe retries, or leave data in an inconsistent state. Test plans should therefore consider access controls, confidentiality of test data, and the security implications of failure behavior. Limit privileges in test environments, protect credentials, and ensure that diagnostic records do not unnecessarily contain personal or confidential information. If testing involves third-party services, respect their operational limits and agreements. These practices help keep reliability assessment controlled while preserving the integrity of the system and the evidence collected.

Trustworthy conclusions require transparent methods. Document what was tested, what was excluded, the environment used, and any deviations from the plan. Distinguish observed facts from assumptions, and state when limited sample size or environmental differences restrict confidence. Independent review can help detect gaps in scenario selection or interpretation, particularly for high-impact software. Security review, privacy assessment, and operational approval may also be required before disruptive testing. No temporary label, test report, or isolated result should be presented as certification unless it has been evaluated under an appropriate, formally defined process.

Why use MAGICQA20261109M 04655 as a reliability review framework

MAGICQA20261109M 04655 serves here as a named publication context for discussing software reliability checks, not as a commercial offering or assurance seal. The useful framework is the disciplined practice behind the discussion: define critical behavior, set measurable criteria, test realistic conditions, monitor outcomes, and preserve evidence. Teams can apply these principles to different architectures while tailoring scenarios to their own risks and service expectations. Before relying on results, verify that test coverage matches the system’s current design and that environment differences are understood. A clear scope and honest limitations make the resulting assessment more useful for engineering and release decisions.

For an effective quality assurance program, treat reliability checks as recurring work throughout development and maintenance. Run focused checks after meaningful changes, revisit assumptions when usage patterns or dependencies change, and review production incidents for scenarios that should be added to future testing. Keep ownership clear so that findings are investigated, resolved, or explicitly accepted rather than left undocumented. The strongest decision is not simply to seek a passing result; it is to understand what the evidence supports, where uncertainty remains, and which next action will reduce meaningful risk.

« Previous Page — Next Page »